Agentic finetuning using a custom harness

The goal was to figure out whether a small model running on my own hardware could do the job of intent classification and structured parameter extraction  well enough for one of my use-cases – read a request like “add 8 spare tent stakes to the camping box” and turn it into something the application can act on.

I created an agentic fine-tuning and evaluation loop with a custom evaluation harness: an AI agent proposes one change at a time, a custom evaluation harness measures it against a frozen test set, and every run gets appended to a log with its settings, result and next decision. The agent does the all the work of dataset generation, training, evaluation and diagnosis.

Setup

I built a fixed test set of 45 requests covering nine intents, five cases each, and froze it. Every model, change and training run was measured against those same 45 cases. The output metrics of each run were: intent accuracy, meaning did it pick the right action, and parameter accuracy, meaning did it extract the right details. A third important number is: fallbacks, the count of cases where the model declined to answer and returned “unclear.”

The OpenAI baseline (gpt-5.6-luna) was created and frozen. It scored 93.33% intent and 71.11% parameter accuracy with no fallbacks.

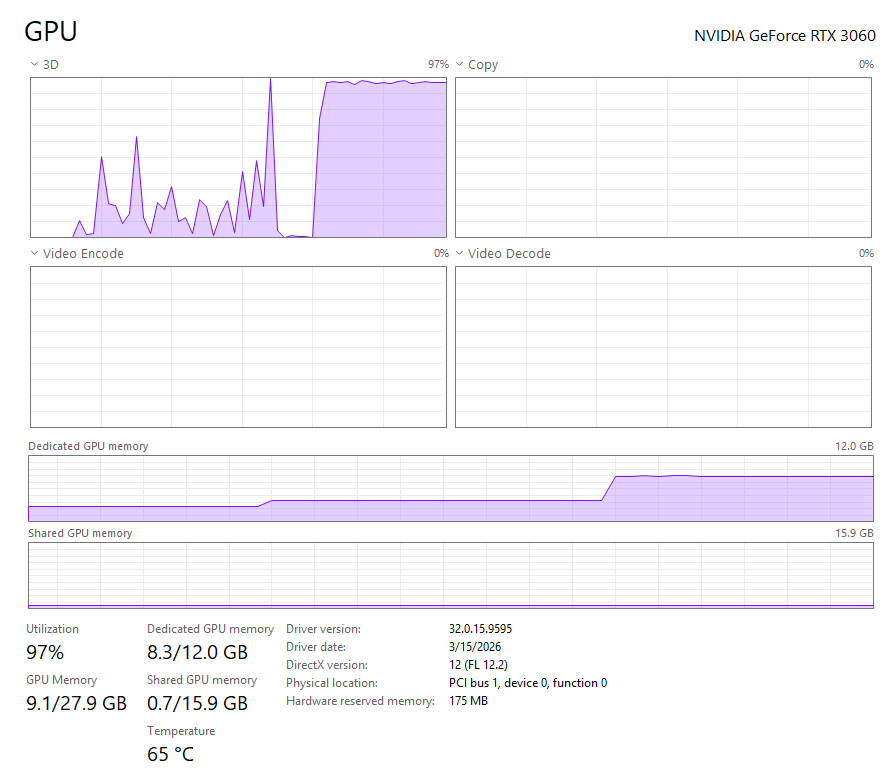
All local training ran on a consumer RTX 3060, in WSL2 with CUDA. LoRA fine-tuning, rank 16, alpha 32, learning rate 1e-4, batch size 4. A 15-epoch run takes about 20 minutes.

The entire source, including training data, eval harness, scripts and agent skill is on GitHub – needle-tuner.
Part 1 – needle2

The first local comparison with needle2 model from Cactus. It scored 4.44% intent accuracy. The problem turned out to be how I was asking the question. I had given the model one abstract, generic “classify this” tool. I replaced it with eight concrete tools, one for each real action the application supports.

The result went to 62.22% intent and 68.89% parameter accuracy.

With this reasonable starting point, I fine-tuned on a small purpose-built training set and ran a structured loop: change one thing, measure against the frozen test set, write down the result.

Needle2 configuration Intent Parameter
Base model, redesigned tools, no training 62.22% 68.89%
Best fine-tuned run (5 epochs, rank 8) 64.44% 62.22%
Longer training (30 epochs) 57.78% 64.44%
Heavier defaults 42.22% 51.11%

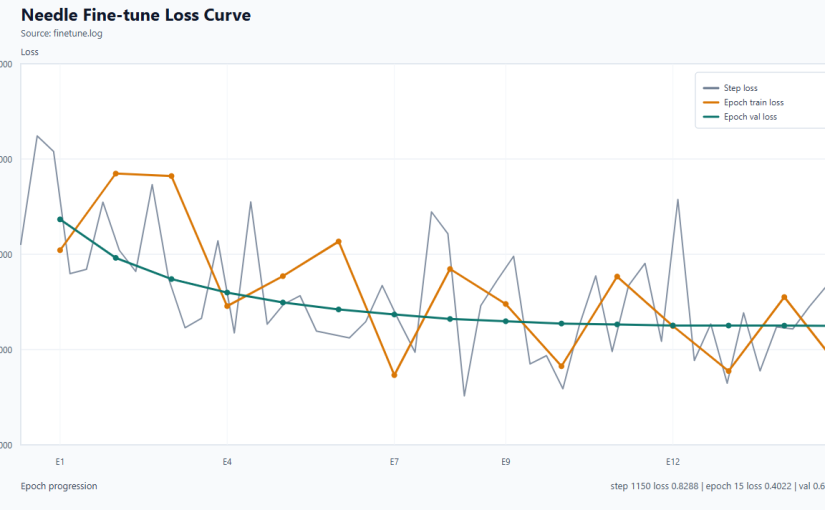
The best training result gained two points on intent accuracy over no training at all, and lost six on parameters. More training made things worse. The heaviest run also refused to answer far more often, with 15 fallbacks against 9 for the untrained model. The results were noisy enough to make any single comparison suspect. Two runs of the identical best configuration measured 64.44% and 60.00%, so I stopped treating one good run as evidence of anything. Validation loss kept improving while held-out accuracy got worse. Had I watched the training dashboard instead of the frozen test set, I would have shipped a regression. I stopped at this point.

Part 2 – needle3

A new version of the model family had shipped in the mean time, with a different architecture and a different native engine. Untrained, needle3 measured 71.11% intent and 66.67% parameter accuracy with 7 fallbacks. I modified the agentic loop to support the new model and executed again.

A one-epoch smoke test scored 68.89% and 73.33%, which is one run on one epoch and proves nothing on its own. A full 30-epoch run at the wrapper defaults scored 71.11% and 66.67%, identical to the untrained base. However, the per-intent breakdown had shifted underneath, some intents up and some down, while the totals stayed flat. Validation loss bottomed out at epoch 13 and climbed for the remaining 17 epochs while training loss kept falling. Same overfitting pattern needle2 had shown.

The issue

Instead of tuning another hyperparameter, I stopped reading aggregate scores and started reading individual failures.

The training data and the held-out test set agreed on which intent was correct. They disagreed on the convention for writing the parameters down.

The first problem was descriptive adjectives. For delete requests, the test set strips condition words from item names, so “the broken toaster” is expected to yield ‘toaster’. All 12 authored delete rows in my training data did the opposite, keeping ‘cracked mixing bowl’ and ‘expired pain reliever’ intact.

The second problem was a wrong key name. For inventory-viewing requests, the training data used a ‘location’ key for the container slot while every other intent, and the test set, used ‘boxLabel’. It also carried a ‘scope’ key that appears in zero held-out cases.

The model was learning my convention faithfully and being marked wrong for it, on 100% of those cases. That also explains why longer training hurt: more epochs meant learning the wrong answer more thoroughly.

The Fix

I corrected 12 delete rows and 20 view-inventory rows, regenerated the derived datasets, re-pinned the integrity hashes and re-ran the validation suite. No hyperparameter change and dropped Epoch count from 30 to 15, taken from the previous run’s validation-loss minimum.

Result: 82.22% intent and 75.56% parameter accuracy, 6 fallbacks.

Run Intent Parameter Fallbacks
Needle2 base 62.22% 68.89% 9
Needle2 best fine-tune 64.44% 62.22% not recorded
Needle3 base 71.11% 66.67% 7
Needle3 fine-tuned, original data, 30 epochs 71.11% 66.67% 6
Needle3 fine-tuned, corrected data, 15 epochs 82.22% 75.56% 6
OpenAI (frozen baseline) 93.33% 71.11% 0

That is 11 points of intent accuracy over its own base model and 20 over needle2‘s base. It is also the first time a local model beat the hosted API on parameter accuracy, 75.56% against 71.11%. Intent accuracy is still 11 points behind.

The per-intent movement matches the diagnosis. Delete went from 80%/40% to 100%/80%. Search went from 60%/60% to 100%/100%. Update improved as well, since the bare-noun convention is shared by every intent that names an item.

Validation loss behaved differently too. With the corrected data it declined every one of the 15 epochs, with none of the mid-run turnaround the unfixed run showed. The contradictory labels had been generating the overfitting signal themselves.

Next

Parameter extraction already beats the API. Intent classification is 11 points behind, and most of the remaining gap sits in one diagnosed failure mode: deciding whether a vague request is actionable.

The next lever is contrastive training examples sitting right on that boundary. After that the options get expensive: changes to how the model produces its answers, training that explicitly teaches it what a wrong answer looks like, or a different architecture.

Hyperparameter tuning and the size of the training dataset should also be revisited to explore further improvements to intent classification.

Because the same 45 cases were used to decide which experiment to run next, they are now a model-selection set rather than an unbiased final exam. Before anyone calls this production-ready it has to be tested against a separate set of cases it has never influenced.

The project also produced a reproducible pipeline along the way. A frozen test set, hash-pinned datasets, a documented training process, a log of every attempt including the failures, and a default path that validates without training and without calling paid APIs. That infrastructure is the reason the annotation issue was discoverable at all.
OpenflowSight – Log Analysis for Snowflake Openflow Telemetry

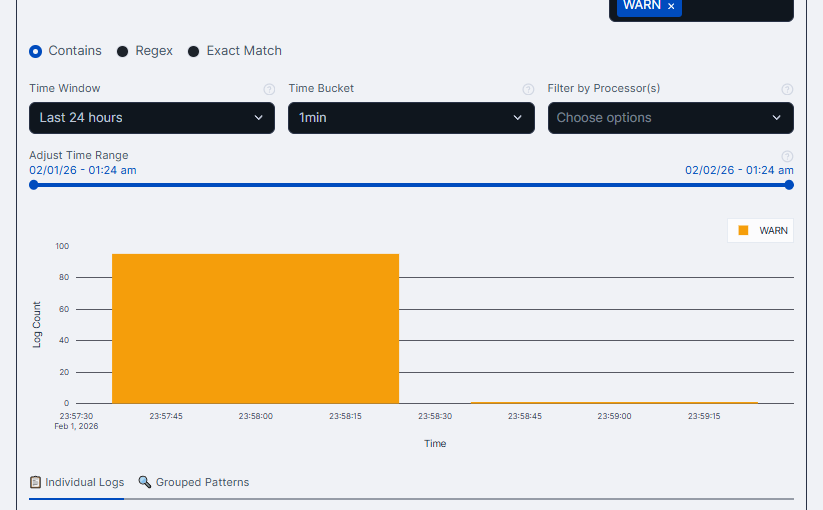
OpenflowSight is a Streamlit application for searching, filtering, and analyzing Openflow telemetry data, inspired by Azure App Insights Search UX.

It’s a log explorer focused on Openflow telemetry. It helps you quickly identify relevant events, see when they spiked, and which processors were involved. Search, group similar events, and export results for deeper offline analysis.

Openflow is an exciting new unified data integration tool from Snowflake based on Apache NiFi. Logs, traces, and metrics emitted at runtime are written to the Event table which supports the OpenTelemetry data model. OpenflowSight surfaces this data to enable convenient, efficient monitoring and analysis of Openflow operations from a graphical dashboard—instead of using SQL queries.

Key Features

  • Runtime Filtering — Select multiple runtimes, toggle system runtimes, filter by processor and log level
  • Smart Search — Multi-term search (comma-separated) with contains, regex, and exact match modes
  • Timeline View — Interactive histogram with zoom/pan, configurable time buckets (1 min to 1 hour), preset windows (1h/6h/24h/7d)
  • Grouped Patterns — Fuzzy clustering that normalizes dynamic values (timestamps, UUIDs) for accurate pattern grouping
  • Individual Logs — Excel-like grid with sorting, filtering, pagination, and multi-select
  • CSV Export — One-click export with smart file naming

Tech Stack

Open Source

OpenflowSight is open-source and contributions are welcome—features, fixes, docs, anything. If it helps you debug Openflow pipelines faster, that’s a win.

View on GitHub →

AI Powered Bookshelf

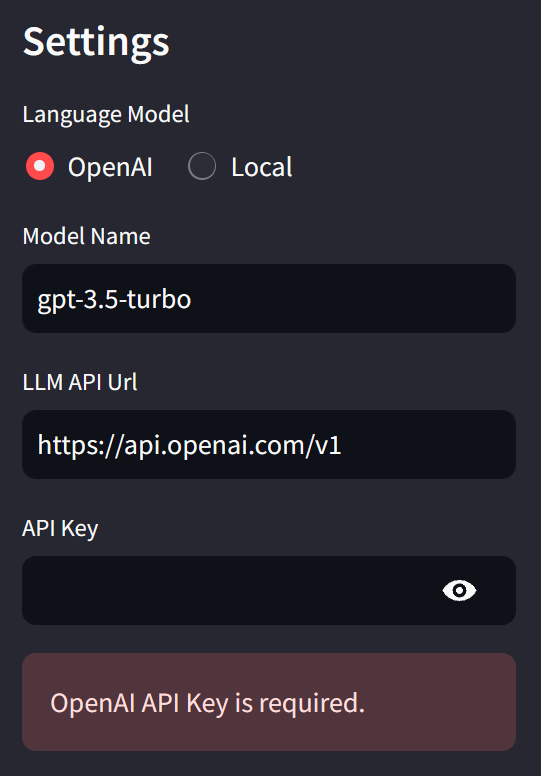
Bookshelf is a Generative AI application built as a rudimentary, but fairly capable, RAG implementation written in python. It can use an open source LLM model (running locally or in the cloud) or a GPT model via OpenAI’s API.

  • The application is created using streamlit.
  • I used llama-index for orchestrating the loading of documents into the vector database. Only TokenTextSplitter is currently used. It does not optimize for PDF, html and other formats.
  • ChromaDb is the vector database to store the embedding vectors and metadata of the document nodes.
  • You can use any open source embeddings model from HuggingFace.
  • Bookshelf will automatically use the GPU when creating local embeddings, if the GPU is available on your machine.
  • You can use OpenAI embeddings as well. There is no way to use a specific OpenAI embedding model or configure the parameters yet.
  • Use OpenAI API or any OpenAI compatible LLM API (using LMStudio, Ollama or text-generation-webui) of your choice.
  • There is a live demo on streamlit cloud – https://bookshelf.streamlit.app/
  • The demo allows only OpenAI integration. You can run it locally for accessing Open Source embedding models and LLMs.

Live demo – https://bookshelf.streamlit.app/

You will need your OpenAI api key for the demo.

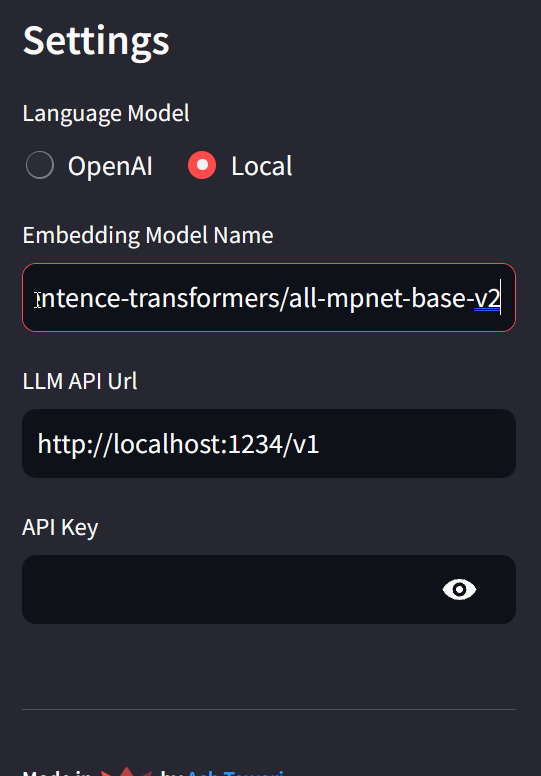
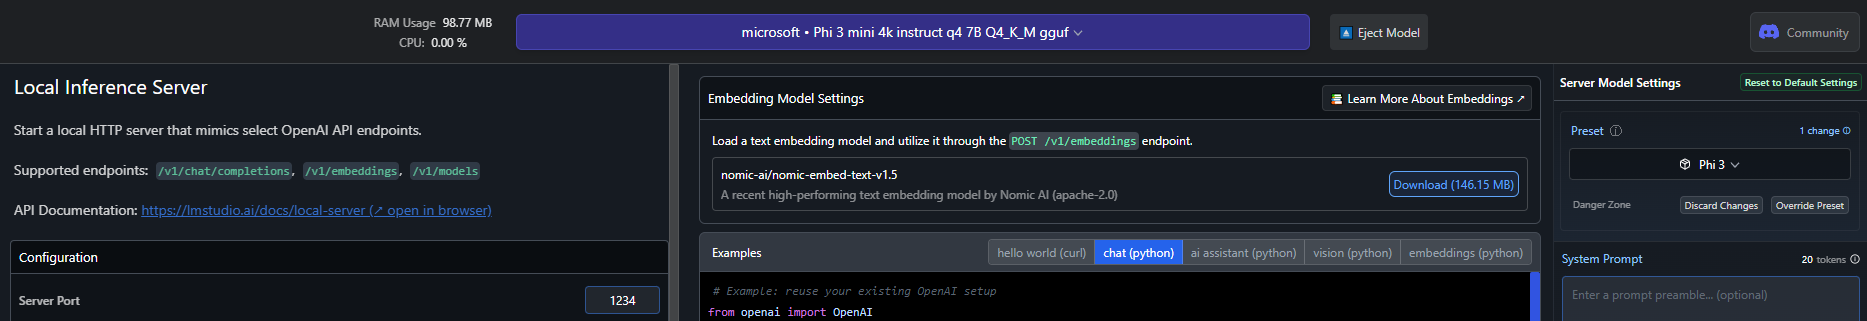
If you are running it locally, you will have the option of using an Open Source LLM instance via an API Url. In the screenshot, I am using an open source Embedding Model from HuggingFace (sentence-transformers/all-mpnet-base-v2) and The local LLM server at http://localhost:1234/v1

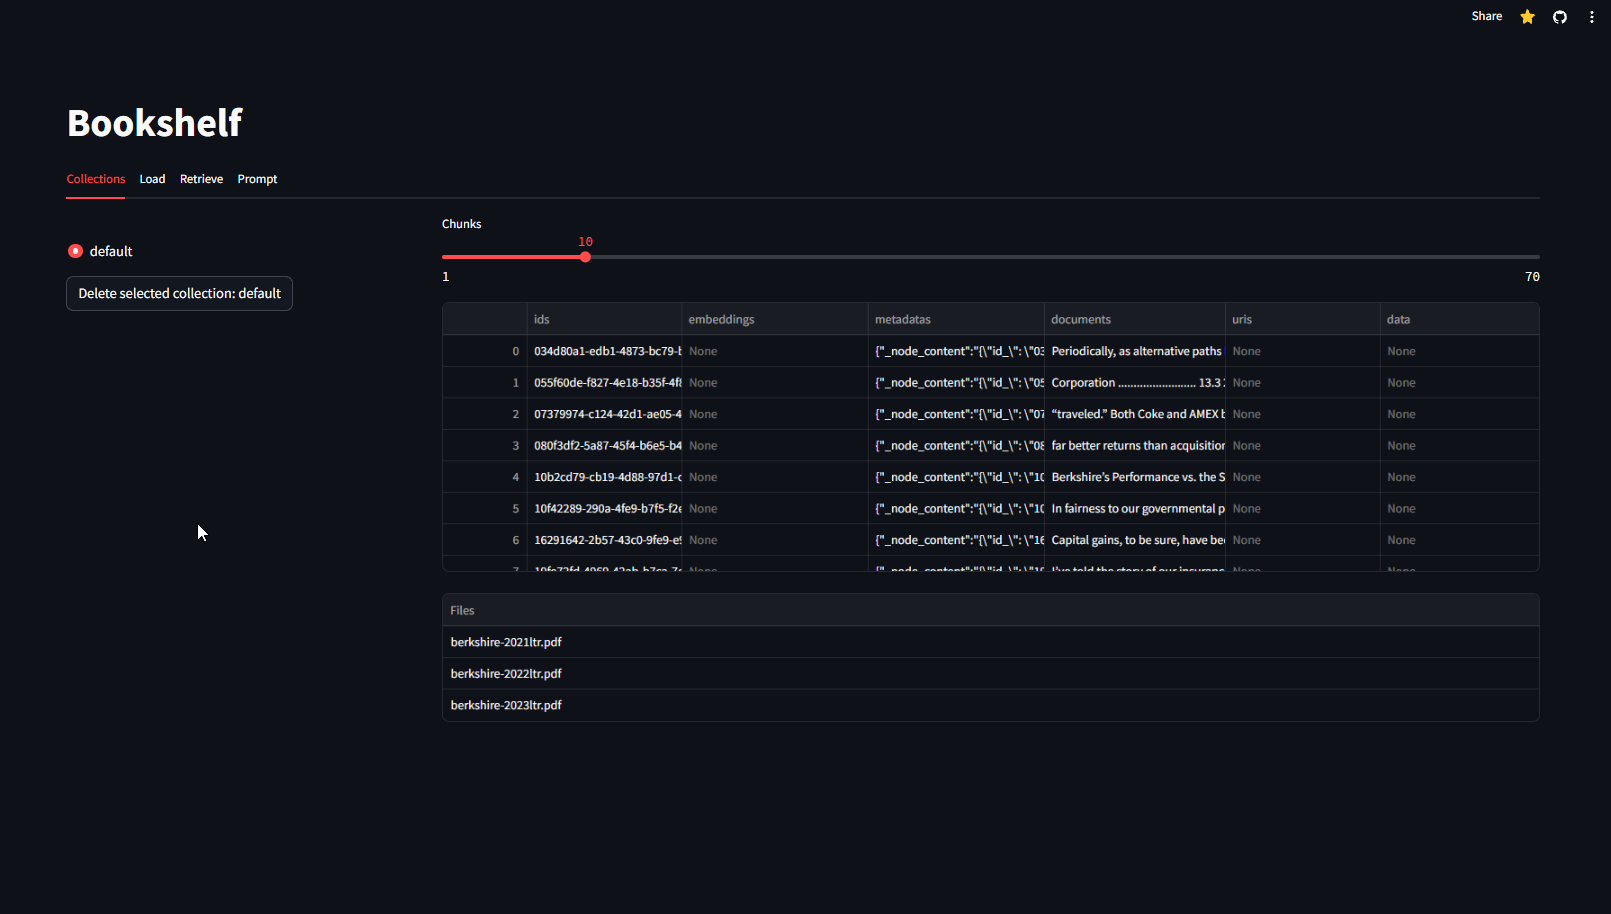
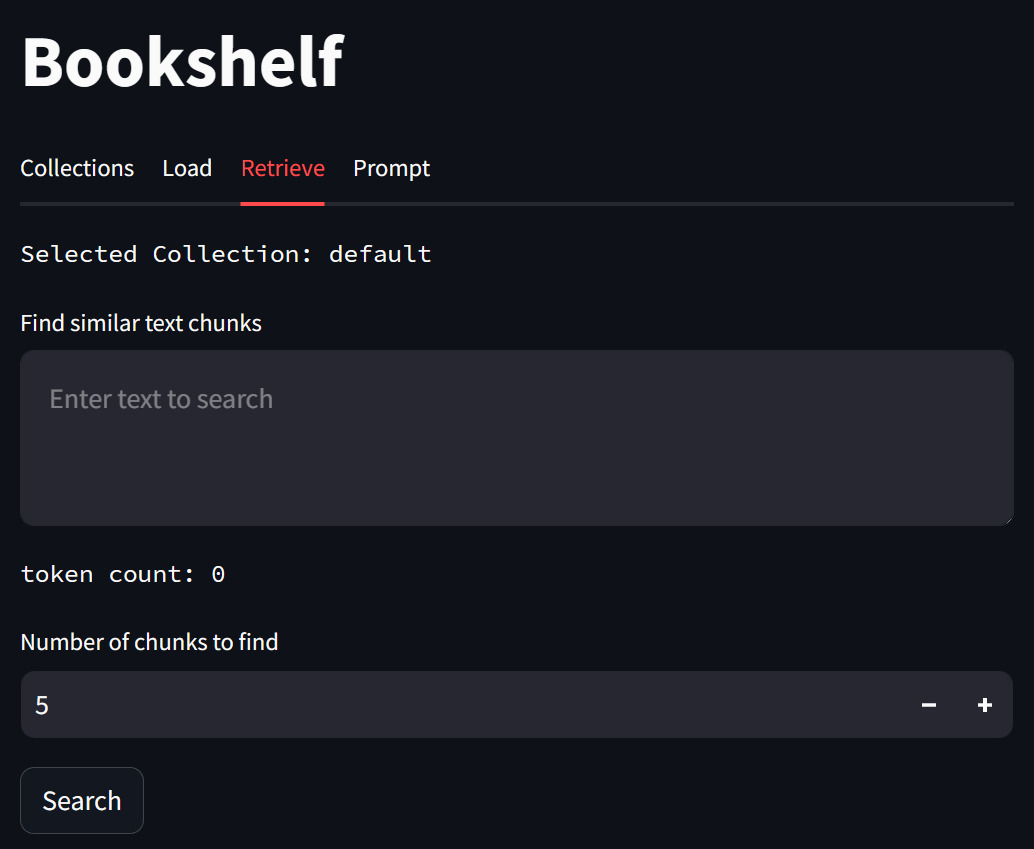
Collections tab shows all collections in the database. It also shows the names of all the files in the selected collection. You can inspect individual chunks for the metadata and text of each chunk. You can delete all contents of the collection (there is no warning).

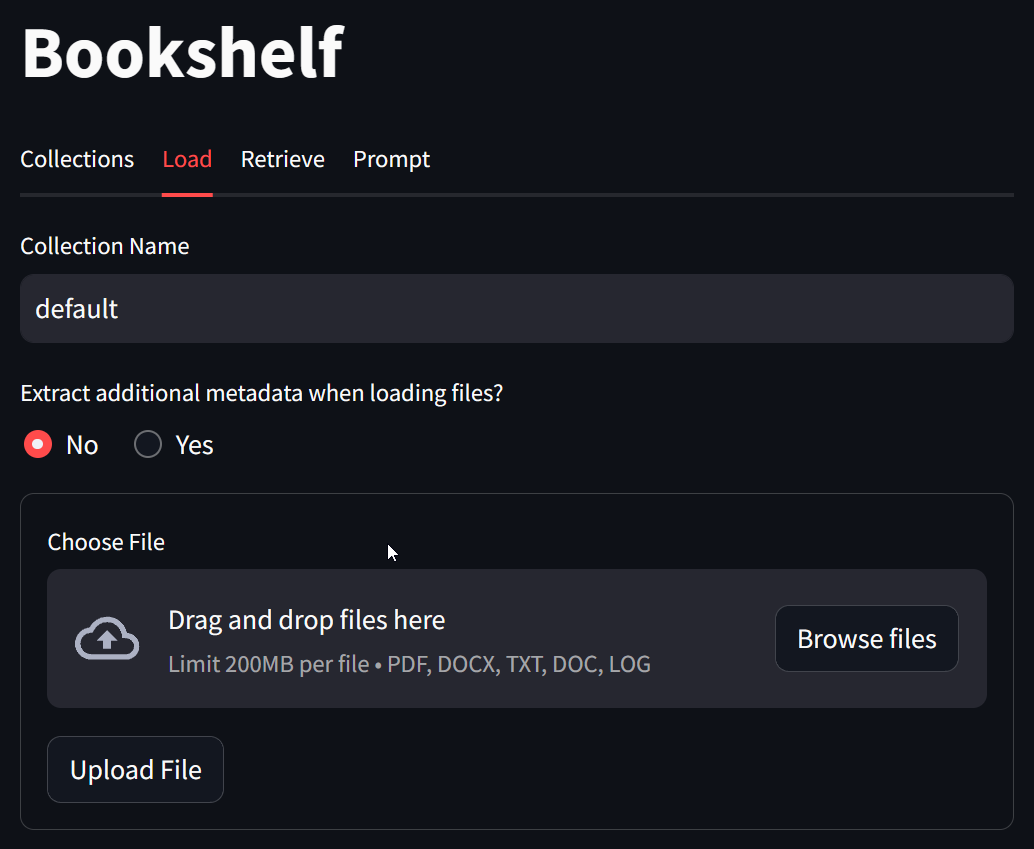
You can modify the collection name to create a new collection. Multiple files can be uploaded at the same time. You can specify if you want to extract metadata from the file contents. Enabling this option can add significant cost because it employs Extractors which use LLM to generate title, summaries, keywords and questions for each document.

On the Retrieve tab, you can query chunks which are semantically related to your query.

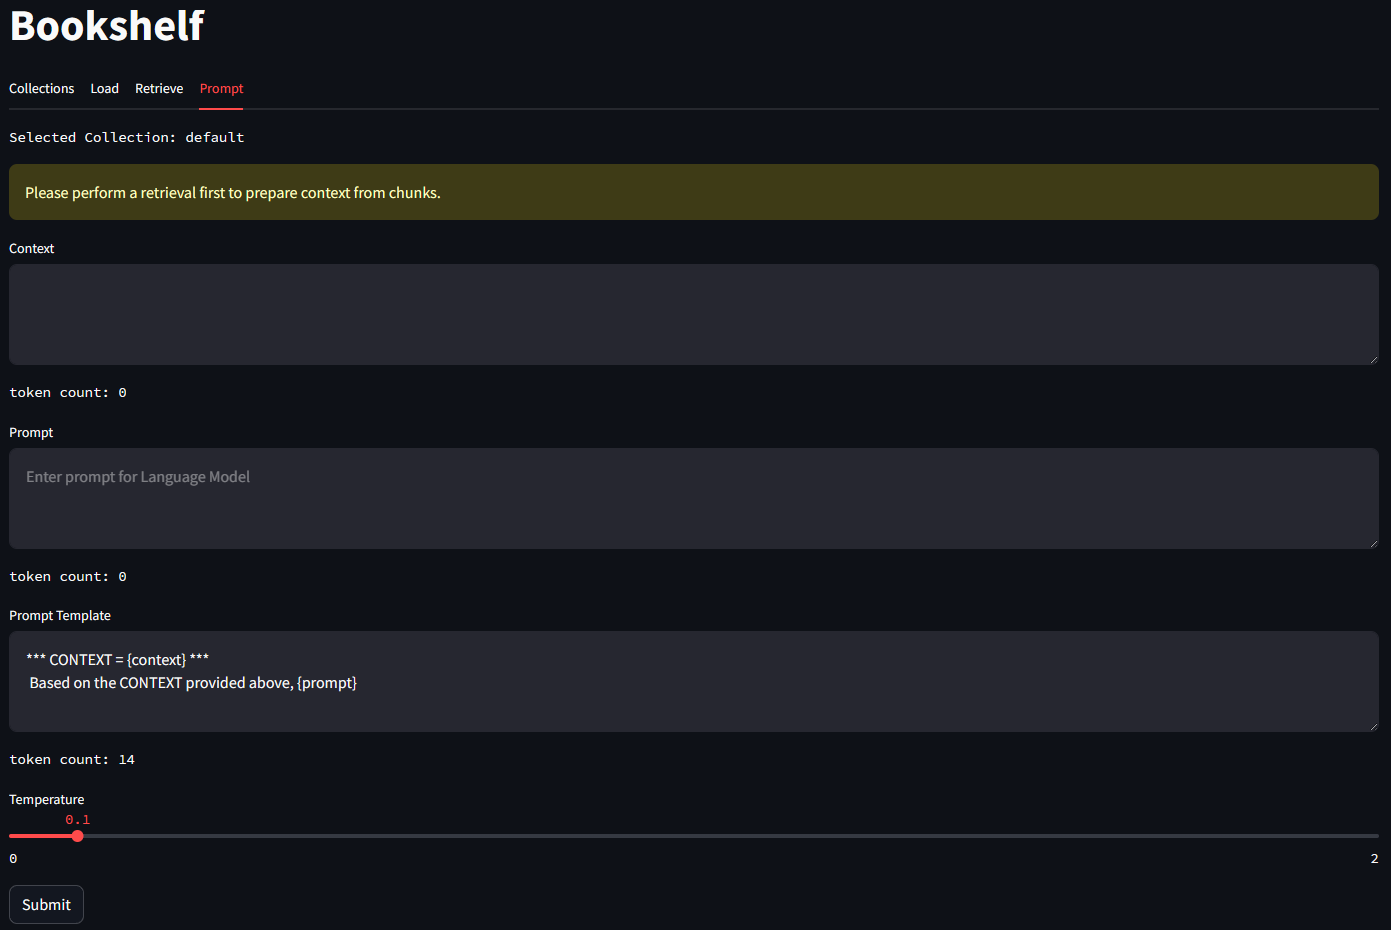
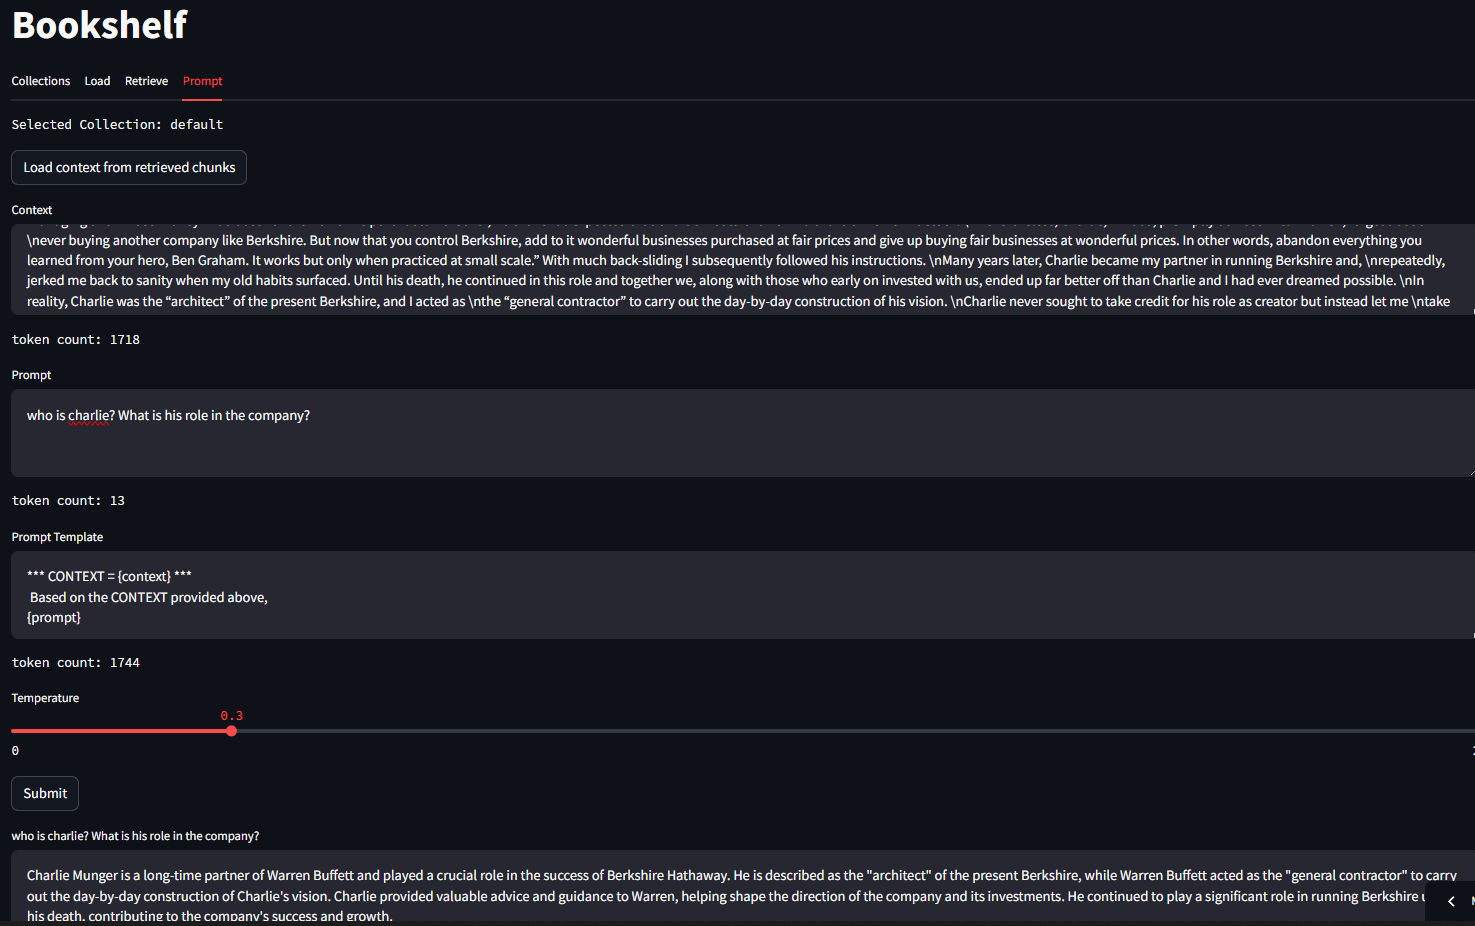
On the Prompt tab, you can prompt your LLM. The context as well as the Prompt Template is editable.

Here is an example of using the context retrieved from chunks in the Vector database to query the LLM.

This inference was performed using Phi3 model running locally on LMStudio.

Code is on Github – https://github.com/ashtewari/bookshelf

Have fun!

KeyNode with Node.js and Microsoft Azure

KeyNode is a application to issue and verify software license keys. Technology stack for KeyNode is Node.js, MongoDB and Microsoft Azure.

I had built this functionality with C9.io (a cloud-based IDE with a built-in source code repository and debugger), mongohq (MongoDB as a service – now part of compose.io) and appfog (Cloud PAAS built on top of CloudFoundry). It used SMTP/gmail to email license files. That was the version I created a couple of years ago to issue tamper-proof signed xml license files for CodeDemo (a code snippet tool for developers, presenters and instructors).

For KeyNode (open source) I switched to a different toolset : Visual Studio Code and Windows Azure, simplified the code to remove signed xml file and open-sourced it on GitHub. Signed xml allowed offline verification in CodeDemo (a Wpf/Desktop app). Removing signed xml requires verification to happen online. I am working on adding the web endpoint for verification of license keys. This version uses SendGrid to email license keys. KeyNode is deployed as a Windows Azure Web App. The Azure Web App is on Continuous Deployment feed from the source code repository on GitHub.

I created and tested this Node.js application locally without IIS and deployed it as an Azure Web App without making any changes to the code at all. Node.js applications are hosted in Azure under IIS with iisnode. Iisnode is a native IIS module that allows hosting of node.js applications in IIS on Windows. Read more about iisnode here. Iisnode architecture also makes it significantly easier to take advantages of scalability afforded by Azure.

KeyNode is a work in progress. My plan is to use this as the basis for further explorations in the following areas :

  • DevOps, Docker and Microservices (at miniature scale of course!)
  • Create a Web UI with Express (a Node.js web application framework)
  • Integrate with Azure Storage/Queues
  • and more…

I invite you to check out the live site on Azure and fork it for your own experiments : KeyNode on GitHub.

Resources :

Photo Credit : Piano Keyboard (www.kpmalinowski.pl)

Using DbUpdater with MySql

DbUpdater can be used with mysql.

Here are the files you need to jumpstart the integration – DbUpdater-MySql.zip

1. You might need to change the path to mysql.exe in mysql-exec.bat.

2. Modify values in mysql-sample-command-line.bat.

Make sure mysql.data.dll is placed in GAC or in the same directory as DbUpdater.exe. Connector binaries can be downloaded from here –
http://dev.mysql.com/downloads/connector/net/6.1.html

Create Games From Scratch

My 18 month old son woke me up at 4 in the morning. I got him to go back to sleep, but … and here I am writing.

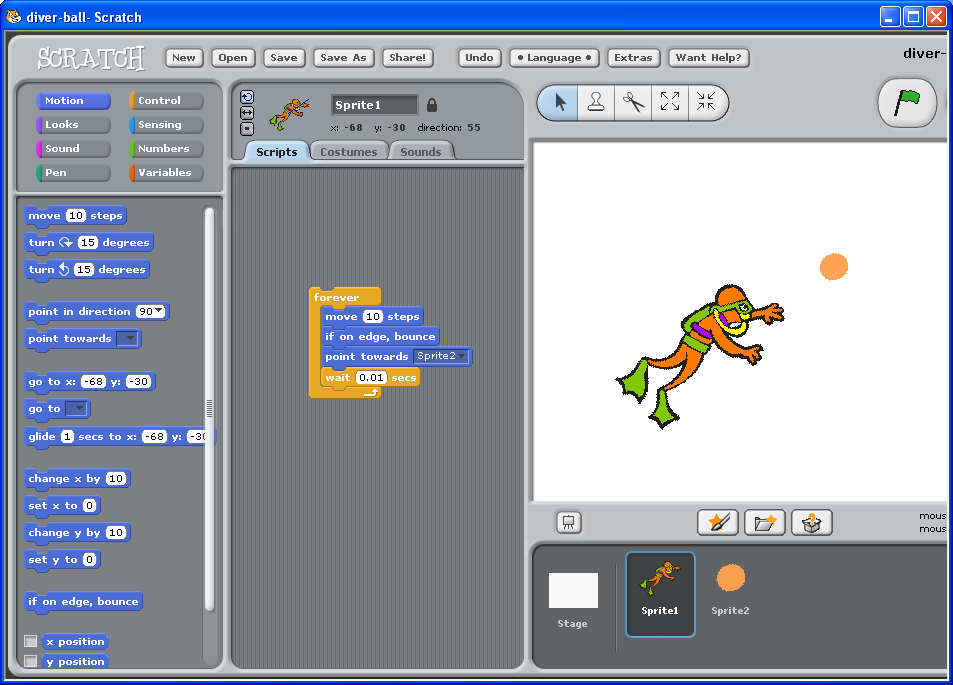
A few weeks ago, I downloaded Scratch from M.I.T’s website. Scratch is a programming language for kids. You drag/drop and (literally) snap together programming constructs to create games. Within a couple of minutes, I had a diver chasing a ball bouncing around on the screen.

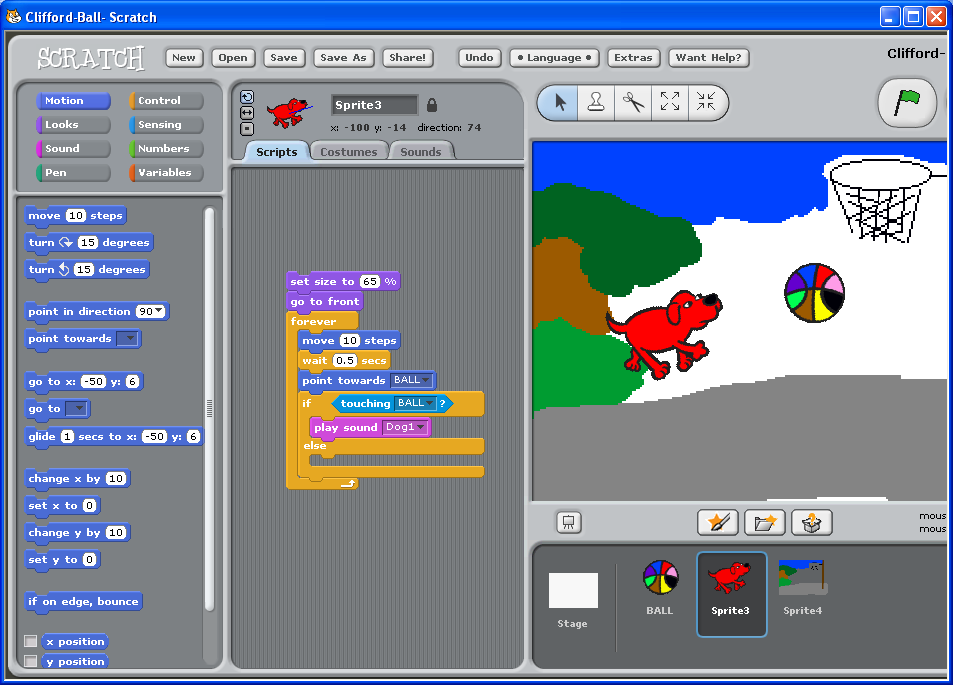
I showed it to my 5 year old son and he watched as I “changed the game” and had the ball chase the mouse cursor and the diver chase the ball. He sat down with me and asked me if I could make it a dog chasing the ball instead. Sure! Then we started customizing further. Make it run faster .. Yeah! Let’s turn him into Clifford – The Big Red Dog … Can he bark ? Sure. Let’s turn it into a basket ball .. I want it red, blue, yellow, … Let’s make a basket ball hoop and have Clifford play basketball … Sure.

It was a quite productive pair programming session 🙂 . No TDD yet – he is too young for that kind of stuff 🙂 .

I was relieved that I didn’t loose his attention while I was “programming”. Now, my son does have a pretty long attention span for his age, but a lot of credit goes to the designers of Scratch. The entire “artwork” was created within the Scratch application and the “programming” was just a pure joy for my son. And we were just “scratching” the surface there. Explore the possibilities here.

You can download the game here : Clifford-ball.sb. Be careful, sometimes the dog turns upside down. There are some bugs to be fixed 🙂 . Where is the debugger ?